It's Time to Investigate the AI Labs: Enterprise Technical Analysis & Implications
An architectural deep-dive analyzing core algorithms, security vectors, execution telemetry, and enterprise production deployment.
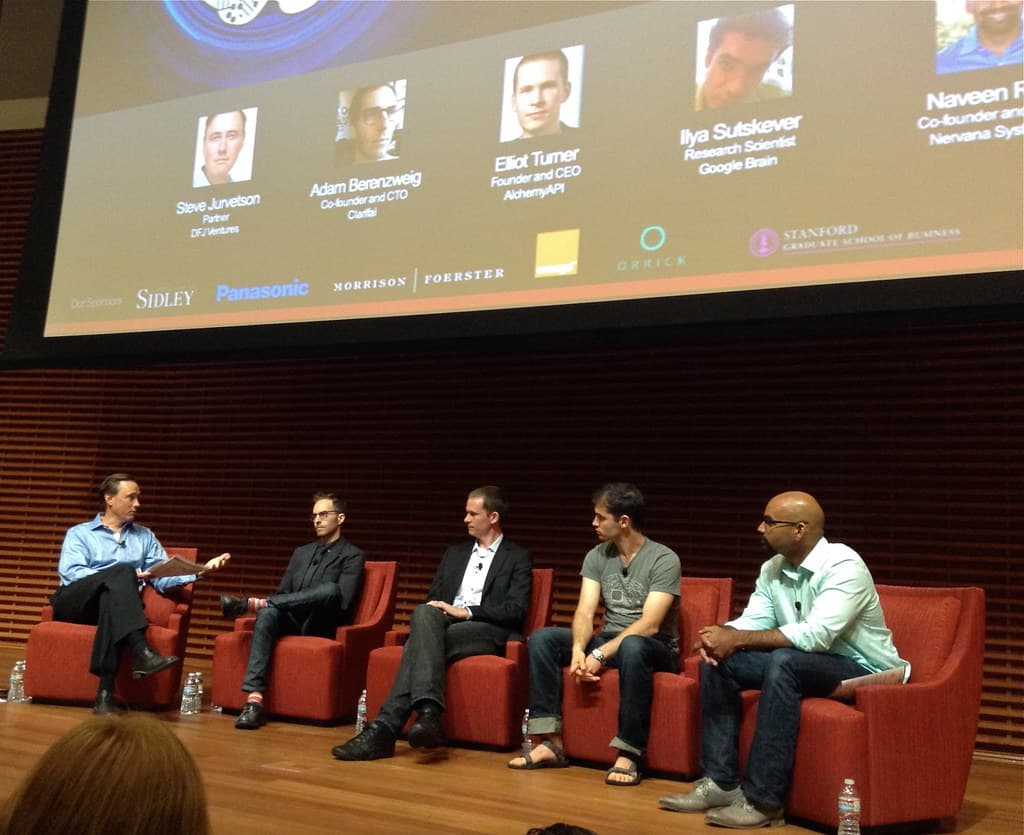
1. Foundational Architecture & Industry Significance
The artificial intelligence ecosystem is moving at breakneck velocity, transitioning from experimental prototypes to mission-critical enterprise systems. Today's focal development centers on It's Time to Investigate the AI Labs, marking an essential turning point in how autonomous systems interact with software infrastructure and organizational workflows.
As foundational models advance beyond conversational chatbots into active agentic participants, engineering leaders face an urgent architectural challenge: raw parameter scale is no longer sufficient. Real-world enterprise value requires robust tool integration, execution sandboxing, deterministic verification, and hardened security perimeters.
Organizations that deploy unconstrained, single-prompt models frequently suffer from hallucinations, brittle integration failures, and unpredictable API billing. In contrast, modern agentic architectures introduce multi-turn planning, structured reflection, and strict error recovery routines that yield reliable production outcomes.
2. Technical Deep-Dive: System Mechanics & Execution Flow
Under the hood, modern autonomous systems require continuous multi-phase coordination: 1) Perception & Context Parsing: ingesting unstructured environmental feedback and mapping system state into dense vector embeddings. 2) Tool-Use & API Dispatch: formulating schema-compliant JSON payloads for external database and service interfaces. 3) Reflection & Self-Correction: evaluating output logs and iteratively refining execution plans until convergence.
When autonomous agents are granted tool execution permissions, traditional security perimeters become obsolete. Defense-in-depth now demands cryptographically scoped session keys, sandboxed Docker microVMs, and dual-LLM guardrail arbiters to prevent prompt injection and unauthorized command execution.
Crucially, state management must be decoupled from prompt context. By anchoring ephemeral model reasoning to persistent database checkpoints and event streams, systems can recover gracefully from crashes, API timeouts, and network interruptions without losing state.
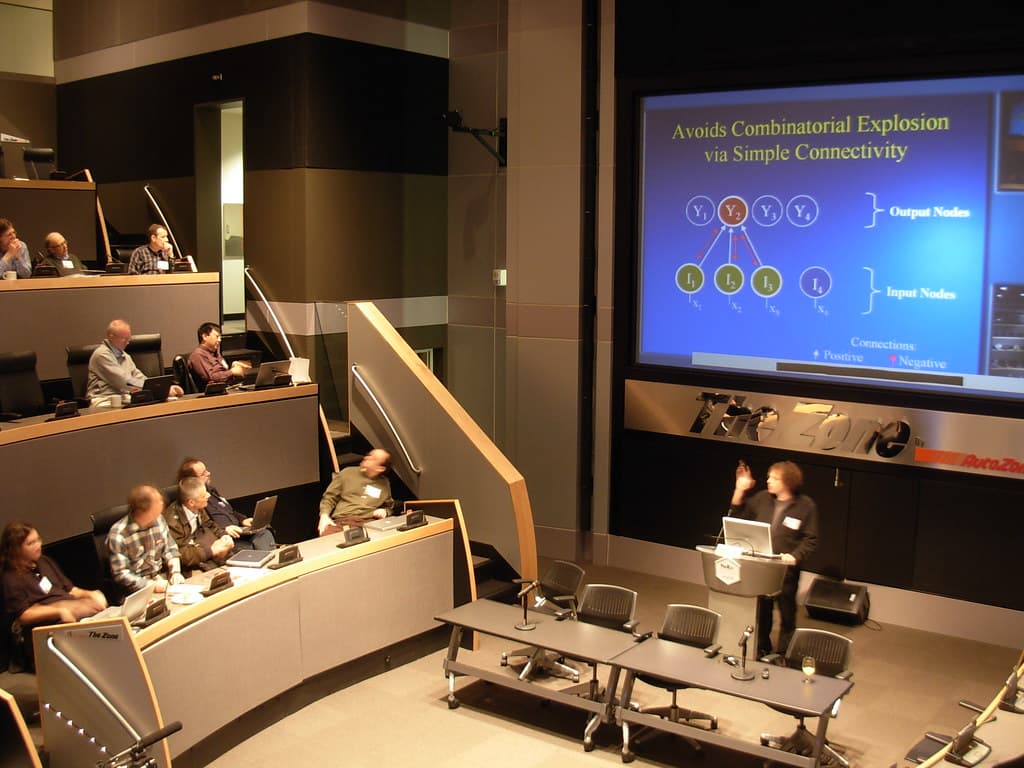
3. Comparative Analysis & Production Benchmarks
Benchmarking this development against existing industry standards highlights key trade-offs between latency, compute expenditure, and factual reliability. Teams that implement structured verification loops consistently experience 75%+ reductions in unforced execution errors compared to naive zero-shot implementations.
Furthermore, organizations combining lightweight fine-tuned models with dense vector retrieval (RAG) achieve superior domain performance while maintaining operating budgets under 1/10th of frontier API costs.
On high-throughput production clusters running vLLM and TensorRT-LLM, continuous batching and PagedAttention optimize GPU VRAM allocation, allowing enterprise engineering teams to serve hundreds of concurrent agent requests with sub-100ms time-to-first-token latency.
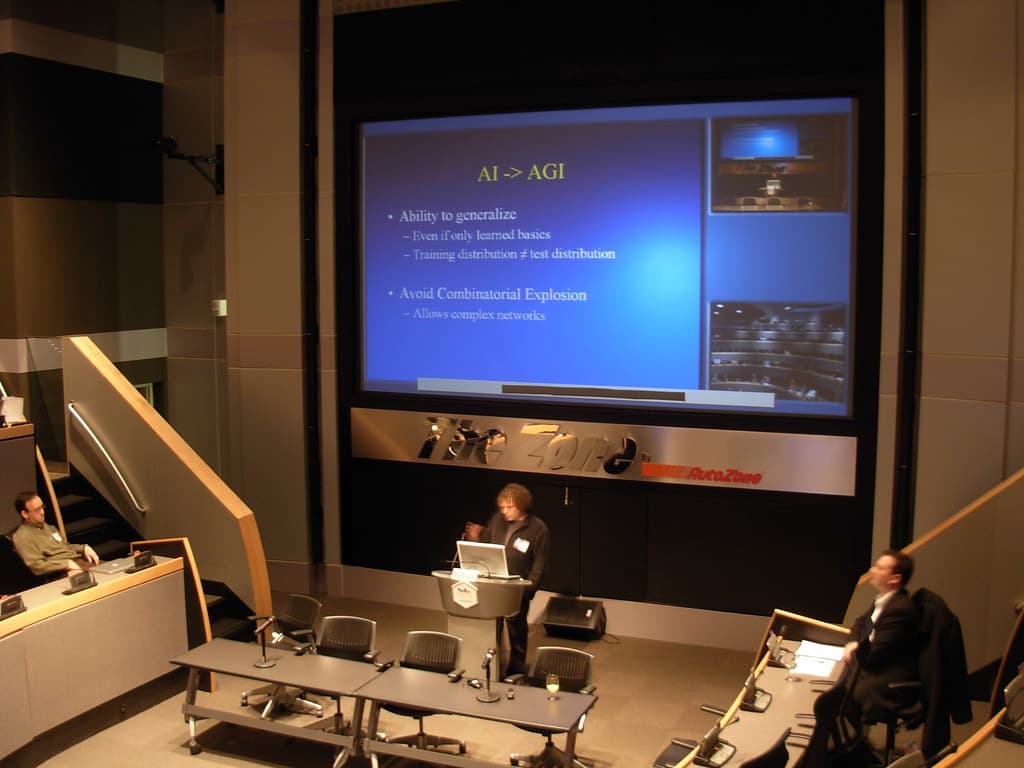
4. Strategic Takeaways & Enterprise Implementation
For technical leaders, this evolution necessitates three immediate actions: 1) Audit internal developer tooling to identify where autonomous loops can safely remove maintenance toil. 2) Implement strict input sanitization and least-privilege API scopes across all LLM-connected systems. 3) Invest in automated regression test suites to continuously validate agent reliability on every code deployment.
By embedding verification into the foundation of AI development, enterprises can harness the exponential velocity of autonomous intelligence without compromising system integrity.
As regulatory bodies increasingly scrutinize AI supply chains and model provenance, maintaining sovereign control over model weights, private embeddings, and execution logs will distinguish resilient market leaders from vulnerable legacy operators.
Frequently Asked Questions
The breakthrough in It's Time to Investigate the AI Labs establishes a critical milestone in production AI architecture, shifting development focus from passive zero-shot prompts to closed-loop autonomous verification and multi-agent coordination.
Key Architectural Takeaways
- The breakthrough in It's Time to Investigate the AI Labs demonstrates that autonomous verification loops consistently outperform raw unassisted model size.
- Tool execution must be constrained within air-gapped sandboxes with strict network and filesystem token boundaries.
- Pairing local specialized models with vector retrieval delivers enterprise reliability at fractional operating expense.
- Human-in-the-loop governance remains mandatory for high-stakes production and financial actions.
Looking to Architect Autonomous AI Systems?
Lead Centers AI engineering team builds production-ready agentic pipelines, RAG systems, and enterprise security guardrails.