Best Open Source LLMs & Local LLMs in 2026: Ollama, LM Studio, Mistral & DeepSeek vs ChatGPT
The definitive guide to running local, private language models on workstations and on-premise cloud GPUs with zero data leakage.
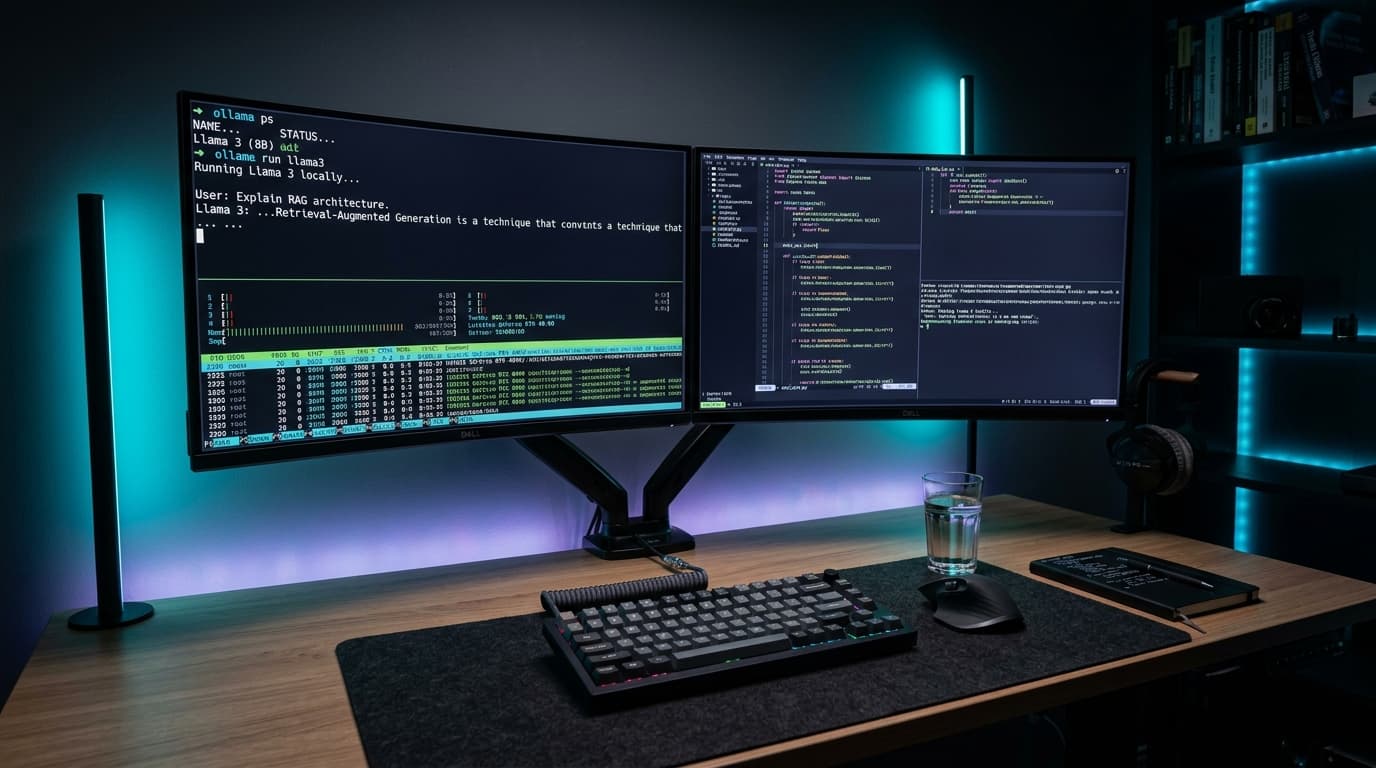
The Rise of Sovereign, Local AI in 2026
The open-source AI revolution has reached parity with commercial cloud APIs. Today, open-weight models from DeepSeek, Mistral AI, and Meta rival GPT-4o in reasoning, math, and software engineering. For enterprises handling proprietary source code, patient healthcare data, or sensitive financial transactions, hosting models locally is now a strict security requirement.
Running models locally completely eliminates data egress to third parties, avoids per-token API billing, bypasses rate limits, and ensures permanent reproducibility even if commercial providers change model behavior.
Top Open Source Models Ranked
Selecting the right open model depends on parameter scale and hardware constraints. DeepSeek-V2.5 has captured developers worldwide thanks to its Mixture-of-Experts (MoE) architecture that only activates 21B parameters out of 236B during inference, delivering frontier performance at high throughput.
For lighter laptops with 16GB RAM, 8B models like Llama 3.1 8B and Mistral 7B quantized in GGUF Q4_K_M run at over 45 tokens per second on Apple M-series chips.
Local Execution Runtimes: Ollama vs LM Studio vs vLLM
Three software runtimes dominate local AI: 1) Ollama: The lightweight, CLI-first engine for Mac, Linux, and Windows with a native OpenAI-compatible REST server. 2) LM Studio: A rich desktop GUI with visual hardware profiling and Hugging Face search. 3) vLLM: The high-concurrency production server featuring PagedAttention and continuous batching for enterprise server clusters.
Pairing vLLM with Docker and Kubernetes allows organizations to serve high-concurrency AI endpoints across internal teams without paying per-token cloud markup.
Frequently Asked Questions
For 7B-8B parameter models quantized in 4-bit GGUF, a laptop with 16GB of unified memory (such as an Apple M-series Mac or an NVIDIA RTX 3060/4060 with 8GB-12GB VRAM) delivers 35–50 tokens per second.
Key Architectural Takeaways
- Open-weight models (DeepSeek, Llama 3.1, Mistral) now match or exceed GPT-4o on standardized coding and reasoning tasks.
- Model quantization (GGUF 4-bit) enables running high-intelligence models locally on 16GB-32GB Apple Silicon or consumer GPUs.
- Ollama provides instant local CLI/REST deployment, while vLLM powers scalable production clusters with PagedAttention.
- Processing millions of internal tokens on dedicated hardware saves 70% to 90% compared to recurring proprietary cloud API subscriptions.
Want to Deploy Private Local AI in Your Organization?
We build on-premise AI infrastructure, configure local LLM runtimes, and connect private vector search for zero-data-leak enterprise security.